Enfabrica MegaNIC, a solution to GPU backend networking #AIFD5

I attended AI FieldDay 5 (AIFD5) last week and there were networking vendors there discussing how their systems dealt with backeng GPU network congestion issues. Most of these were traditional vendor congestion solutions.

However, one vendor, Enfabrica, (videos of their session will be available here) seemed to be going down a different path, which involved a new ASIC design destined to resolve all the congestion, power, and performance problems inherent in current backend GPU Ethernet networks.

In essence, Enfabrica’s Super or MegaNIC (they used both terms during their session) combines PCIe lanes switching, Ethernet networking, and ToR routing with SDN (software defined networking) programability to connect GPUs directly to a gang of Ethernet links. This allows it to replace multiple (standard/RDMA/RoCEv2) NIC cards with one MegaNIC using their ACF-S (Advanced Compute Fabric SuperNic) ASIC.

Their first chip, codenamed “Millennium” supports 8Tbps bandwidth.

Their ACF-S chip provides all the bandwidth needed to connect up to 4 GPUs to 32/16/8/4-100/200/400/800Gbps links. And because their ACF-S chip controls and drives all these network connections, it can better understand and deal with congestion issues backend GPU networks. And it is PCIe 5/6 compliant, supporting 128-160 lanes.

Further, it has onboard ARM processing to handle its SDN operations, onboard hardware engines to accelerate networking protocol activity and network and PCIe switching hardware to support directly connecting GPUs to Ethernet links.

With its SDN, it supports current RoCE, RDMA over TCP, UEC direct, etc. network protocols.

It took me (longer than it should) to get my head around what they were doing but essentially they are supporting all the NIC-TOR functionality as well as PCIe functionality needed to connect up to 4 GPUs to a backend Ethernet GPU network.

On the slide above I was extremely skeptical of the Every 10^52 Years “job failures due to NIC RAIL failures”. But Rochan said that these errors are predominantly optics failures and as both the NIC functionality and ToR switch functionality is embedded in the ACF-S silicon, those faults should not exist.

Still 10^52 years is a long MTBF rate (BTW, the universe is only 10^10 years old). And there’s still software controlling “some” of this activity. It may not show up as a “NIC RAIL” failure, but there will still be “networking” failures in any system using ACF-S devices.

Back to their solution. What this all means is you can have one less hop in your backend GPU networks leading to wider/flatter backend networks and a lot less congestion on this network. This should help improve (GPU) job performance, networking performance and reduce networking power requirements to support your 100K GPU supercluster.

At another session during the show, Arista (videos will be available here) said that just the DSP/LPO optics alone for a 100K GPU backend network will take a 96/32 MW of power. Unclear whether this took into consideration within rack copper connections. But anyway you cut it, it’s a lot of power. Of course the 100K GPUs would take 400MW alone (at 4KW per GPU).

Their ACF-S driver has been upstreamed into standard CCL and Linux distributions, so once installed (or if you are at the proper versions of CCL & Linux software), it should support complete NCCL (NVIDIA Collective Communications Library) stack compliance.

And because, with its driver installed and active, it talks standard Ethernet and standard PCIe protocols on both ends, it is should fully support any other hardware that comes along attaching to these networks or busses (CXL perhaps)

The fact that this may or may not work with other (GPU) accelerators seems moot at this point as NVIDIA owns the GPU for AI acceleration market. But the flexibility inherent in their own driver AND on chip SDN, indicates for the right price, just about any communications link software stack could be supported.

After spending most of the rest of AIFD5 discussing how various vendors deal with congestion for backend GPU networks, having startup on the stage with a different approach was refreshing.

Whether it reaches adoption and startup success is hard to say at this point. But if it delivers on what it seems capable of doing for power, performance and network flexibility, anybody deploying new greenfield GPU superclusters ought to take a look at Enfabricas solution. .

MegaNIC/ACF-S pilot boxes are available for order now. No indication as to what these would cost but if you can afford 100K GPUs it’s probably in the noise…

~~~~

Comments?

#VMworld day 1, Cloud Foundation and Cross-Cloud Services

The main keynote topic for today at VMworld was how to address the coming cloud tsunami. Pat citing his own researchers believes that 50% of all workloads (OS instances) will be running in public and private cloud by 2021 and by 2030, 50% of all workloads will be running in the Public Cloud alone. So today VMware announced two new offerings: VMware Cloud Foundation and VMware Cross-Cloud Services.

Cloud Foundation

Cloud Foundation appears to be a bundling of VMware’s SDDC, NSX®, Virtual SAN™ (VSAN) and vSphere® solutions, into a single, integrated stack/package that can be sold and licensed together. No pricing was provided at the show but essentially VMware want’s to allow customers a simple way to deploy a VMware private cloud.

VMware states that Cloud Foundation offers customers up to 6-8X faster cloud deployment at a TCO savings of >40%.

VMware also announced a joint partnership with IBM to sell Cloud Foundation services residing on the IBM Cloud to their customer base. This broaden’s the availability of VMware cloud service offerings beyond vCloud and on premises Cloud Foundation environments.

Cross-Cloud Services

IMG_6819Everyone wants to minimize cloud vendor lockin but that’s not possible today except in a few special cases (NetApp Private Storage and similar capabilities from other vendors, cloud storage gateway services, cloud archive services, etc.).

VMware Cross-Cloud Services is the next step down this path, attempting to provide easier workload/data migration, consolidated cost and workload management and security deployment across the public and private cloud boundaries.

Cross-Cloud Services was in tech preview at the show but it’s intended to make use of standard public cloud defined APIs to provide specialized targeted services to allow better cross-cloud migration and management.

The tech preview showed VMware Cross-Cloud Services deploying an NSX gateway in AWS which allowed NSX to control public cloud IP addresses and then once that was done, one could apply security templates to deploy network encryption between apps and its services. VMware used a sniffer to show the before plain text traffic and the after with encrypted traffic, all done in a matter of minutes. They also showed cost trending information for workloads running across the private and public cloud.

Next they showed a demo (movie) of VMware migrating/cloning a simple app to other public and private cloud environments. They had a public cloud Unicycle IOT app running in Ireland/AWS (I think) with a three tier (web, app, database) app structure/instances and then migrated/cloned that single site 3-tier app to be deployed across multiple cloud (web and app tiers) sites with a single database instance running in a private cloud.

I started thinking this is getting us down the path towards cloud virtualization but in the end, it’s much more targeted services, which run in instances/gateways in the public and private cloud to do very specific migration or management activities. Nonetheless a great first step towards more flexible cross-cloud deployment and management.

VMworld Day 2 looks to be more on current products and enhancements, stay tuned.

Comments?

Pure Storage FlashBlade well positioned for next generation storage

IMG_6344Sometimes, long after I listen to a vendor’s discussion, I come away wondering why they do what they do. Oftentimes, it passes but after a recent session with Pure Storage at SFD10, it lingered.

Why engineer storage hardware?

In the last week or so, executives at Hitachi mentioned that they plan to reduce  hardware R&D activities for their high end storage. There was much confusion what it all meant but from what I hear, they are ahead now, and maybe it makes more sense to do less hardware and more software for their next generation high end storage. We have talked about hardware vs. software innovation a lot (see recent post: TPU and hardware vs. software innovation [round 3]).
Continue reading “Pure Storage FlashBlade well positioned for next generation storage”

Platform9, a whole new way to run OpenStack

logo-long2
At TechFieldDay 10 (TFD10), in Austin this past week we had a presentation from Platform9‘s Shirish Raghuram Co-founder and CEO and Bich Le, Co-founder and Chief Architect. Both Shirish and Bich seemed to have come from having  worked a long time at VMware and prior to that, other tech giants.

Platform9 provides a user friendly approach to running OpenStack in your data center. Their solution is a SaaS based, management portal or control plane for running compute, storage and networking infrastructure under OpenStack, the open source cloud software.

Importing running virtualization environments

If you have a current, running VMware vSphere environment, you can onboard or import portions of or all of your VMs, datastores, NSX nodes, and the rest of the vSphere cluster and have them all come up as OpenStack core compute instances, Cinder storage volumes, and use NSX as a replacement for Neutron networking nodes.

In this case, once your vSphere environment is imported, users can fire up more compute instances, terminate ones they have, allocate more Cinder volumes, etc. all from an AWS-like management portal.  It’s as close to an AWS console as I have seen.

Platform9 also works for KVM environments, that is you can import currently running KVM environments into OpenStack and run them from their portal.

Makes OpenStack, almost easy to run/use/operate

Historically, the problem with OpenStack was its user interface. Platform9 solves this problem and makes it easy to import, use, and deploy VMware and KVM environments into an OpenStack framework. Once there, users and administrators have the same level of control that AWS and Microsoft Azure users have, i.e., fire up compute instances, allocate storage volumes and attach the two together, terminate the compute activities, detach the volumes and repeat, all in your very own private cloud.

Bare metal OpenStack support too

If you don’t have a current KVM or VMware environment, Platform9 will deploy a KVM virtualization environment on bare metal servers and storage and use that for your OpenStack cloud.

Security comes from tenant attributes, certain tenants have access and control over certain compute/storage/networking instances.

Customers can also use Platform9 as a replacement for vCenter, and once deployed under OpenStack, tenants/users have control over their segments of the private cloud deployment.

It handles multiple vSphere & KVM clusters as well and can also handle mixed virtualization environments within the same OpenStack cloud.

A few things missing

The only things I found missing from the Platform9 solution was Swift Object storage support and support for Hyper-V environments.

The Platform9 team mentioned that multi-region support was scheduled to come out this week, so then your users could fire up compute and storage instances across your world wide data centers, all from a single Platform9 management portal.

Pricing for the Platform9 service is on a socket basis, with volume pricing available for larger organizations.

If you are interested in a private cloud and are considering  OpenStack in order to avoid vendor lock-in, I would find it hard not to give Platform9 a try.

While at Dell


Later in the week, at TFD10 we talked with Dell, and they showed off their new VRTX Server product. Dell’s VRTX server is a very quiet, 4-server, 48TB tower or rackmount enclosure, which would make a very nice 8 or 16 socket CPU, private cloud for my home office environment (the picture doesn’t do it justice). And with a Platform9 control plane, I could offer OpenStack cloud services out of my home office, to all my neighbors around the world, for a fair but high price…

Comments?


When 64 nodes are not enough

Why would VMware with years of ESX development behind them want to develop a whole new virtualization system for Docker and other container frameworks. Especially since they already have a compatible Docker support in their current product line.

The main reason I can think of is that a 64 node cluster may be limiting to some container services and the likelihood of VMware ESX/vSphere to supporting 1000s of nodes in a single cluster seems pretty unlikely. So given that more and more cloud services are being deployed across 1000s of nodes using container frameworks, VMware had to do something or say goodbye to a potentially lucrative use case for virtualization.

Yes over time VMware may indeed extend vSphere clusters to 128 or even 256 nodes but by then the world will have moved beyond VMware services for these services and where will VMware be then – left behind.

Photon to the rescue

With the new Photon system VMware has an answer to anyone that needs 1000 to 10,000 server cluster environments. Now these customers can easily deploy their services on a VMware Photon Platform which is was developed off of ESX but doesn’t have any cluster limitations of ESX.

Thus, the need for Photon was now. Customers can easily deploy container frameworks that span 1000s of nodes. Of course it won’t be as easy to manage as a 64 node vSphere cluster but it will be easy automated and easier to deploy and easier to scale when necessary, especially beyond 64 nodes.

The claim is that the new Photon will be able to support multiple container frameworks without modification.

So what’s stopping you from taking on the Amazons, Googles, and Apples of the worlds data centers?

  • Maybe storage, but then there’s ScaleIO, and the other software defined storage solutions that are there to support local DAS clusters spanning almost incredible sizes of clusters.
  • Maybe networking, I am not sure just where NSX is in the scheme of things but maybe it’s capable of handling 1000s of nodes and maybe not but networking could be a clear limitation to what how many nodes can be deployed in this sort of environment.

Where does this leave vSphere? Probably continuation of the current trajectory, making easier and more efficient to run VMware clusters and over time extending any current limitations. So for the moment two development streams based off of ESX and each being enhanced for it’s own market.

How much of ESX survived is an open question but it’s likely that Photon will never see the VMware familiar services and operations that is readily available to vSphere clusters.

Comments?

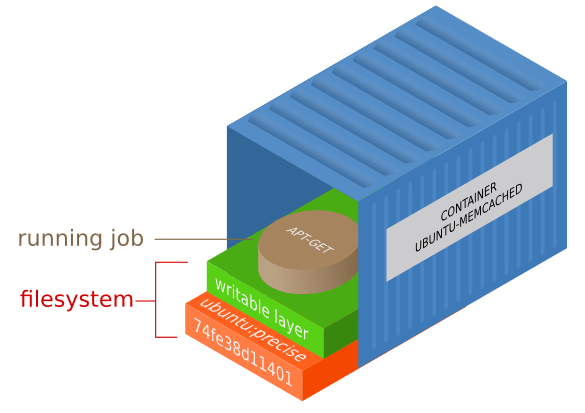
Photo Credit(s): A first look into Dockerfile system

VMworld 2014 projects Marvin, Mystic, and more

IMG_2902[This post was updated after being published to delete NDA material – sorry, RL] Attended VMworld2014 in San Francisco this past week. Lots of news, mostly about vSphere 6 beta functionality and how the new AirWatch acquisition will be rolled into VMware’s End-User Computing framework.

vSphere 6.0 beta

Virtual Volumes (VVOLs) is in beta and extends VMware’s software-defined storage model to external NAS and SAN storage.  VVOLs transforms SAN/NAS  storage into VM-centric devices by making the virtual disk a native representation of the VM at the array level, and enables app-centric, policy-based automation of SAN and NAS based storage services, somewhat similar to the capabilities used in a more limited fashion by Virtual SAN today.

Storage system features have proliferated and differentiated over time and to be able to specify and register any and all of these functional nuances to VMware storage policy based management (SPBM) service is a significant undertaking in and of itself. I guess we will have to wait until it comes out of beta to see more. NetApp had a functioning VVOL storage implementation on the show floor.

Virtual SAN 1.0/5.5 currently has 300+ customers with 30+ ready storage nodes from all major vendors, There are reference architecture documents and system bundles available.

Current enhancements outside of vSphere 6 beta

vRealize Suite extends automation and monitoring support for a broad mix of VMware and non VMware infrastructure and services including OpenStack, Amazon Web Services, Azure, Hyper-V, KVM, NSX, VSAN and vCloud Air (formerly vCloud Hybrid Services), as well as vSphere.

New VMware functionality being released:

  • vCenter Site Recovery Manager (SRM) 5.8 – provides self service DR through vCloud Automation Center (vRealize Automation) integration, with up to 5000 protected VMs per vCenter and up to 2000 VM concurrent recoveries. SRM UI will move to be supported under vSphere’s Web Client.
  • vSphere Data Protection Advanced 5.8 – provides configurable parallel backups (up to 64 streams) to reduce backup duration/shorten backup windows, access and restore backups from anywhere, and provides support for Microsoft Exchange DAGs, and SQL Clusters, as well as Linux LVMs and EXT4 file systems.

VMware NSX 6.1 (in beta) has 150+ customers and provides micro segmentation security levels which essentially supports fine grained security firewall definitions almost at the VM level, there are over 150 NSX customers today.

vCloud Hybrid Cloud Services is being rebranded as vCloud Air, and is currently available globally through data centers in the US, UK, and Japan. vCloud Air is part of the vCloud Air Network, an ecosystem of over 3,800 service providers with presence in 100+ countries that are based on common VMware technology.  VMware also announced a number of new partnerships to support development of mobile applications on vCloud Air.  Some additional functionality for vCloud Air that was announced at VMworld includes:

  • vCloud Air Virtual Private Cloud On Demand beta program supports instant, on demand consumption model for vCloud services based on a pay as you go model.
  • VMware vCloud Air Object Storage based on EMC ViPR is in beta and will be coming out shortly.
  • DevOps/continuous integration as a service, vRealize Air automation as a service, and DB as a service (MySQL/SQL server) will also be coming out soon

End-User Computing: VMware is integrating AirWatch‘s (another acquisition) enterprise mobility management solutions for mobile device management/mobile security/content collaboration (Secure Content Locker) with their current Horizon suite for virtual desktop/laptop support. VMware End User Computing now supports desktop/laptop virtualization, mobile device management and security, and content security and file collaboration. Also VMware’s recent CloudVolumes acquisition supports a light weight desktop/laptop app deployment solution for Horizon environments. AirWatch already has a similar solution for mobile.

OpenStack, Containers and other collaborations

VMware is starting to expand their footprint into other arenas, with new support, collaboration and joint ventures.

A new VMware OpenStack Distribution is in beta now to be available shortly, which supports VMware as underlying infrastructure for OpenStack applications that use  OpenStack APIs. VMware has become a contributor to OpenStack open source. There are other OpenStack distributions that support VMware infrastructure available from HP, Cannonical, Mirantis and one other company I neglected to write down.

VMware has started a joint initiative with Docker and Pivotal to broaden support for Linux containers. Containers are light weight packaging for applications that strip out the OS, hypervisor, frameworks etc and allow an application to be run on mobile, desktops, servers and anything else that runs Linux O/S (for Docker Linux 3.8 kernel level or better). Rumor has it that Google launches over 15M Docker containers a day.

VMware container support expands from Pivotal Warden containers, to now also include Docker containers. VMware is also working with Google and others on the Kubernetes project which supports container POD management (logical groups of containers). In addition Project Fargo is in development which is VMware’s own lightweight packaging solution for VMs. Now customers can run VMs, Docker containers, or Pivotal (Warden) containers on the same VMware infrastructure.

AT&T and VMware have a joint initiative to bring enterprise grade network security, speed and reliablity to vCloud Air customers which essentially allows customers to use AT&T VPNs with vCloud Air. There’s more to this but that’s all I noted.

VMware EVO, the next evolution in hyper-convergence has emerged.

  • EVO RAIL (formerly known as project Marvin) is appliance package from VMware hardware partners that runs vSphere Suite and Virtual SAN and vCenter Log Insight. The hardware supports 4 compute/storage nodes in a 2U tall rack mounted appliance. 4 of these appliances can be connected together into a cluster. Each compute/storage node supports ~100VMs or ~150 virtual desktops. VMware states that the goal is to have an EVO RAIL implementation take at most 15 minutes from power on to running VMs. Current hardware partners include Dell, EMC (formerly named project Mystic), Inspur (China), Net One (Japan), and SuperMicro.
  • EVO RACK is a data center level hardware appliance with vCloud Suite installed and includes Virtual SAN and NSX. The goal is for EVO RACK hardware to support a 2hr window from power on to a private cloud environment/datacenter deployed and running VMs. VMware expects a range of hardware partners to support EVO RACK but none were named. They did specifically mention that EVO RACK is intended to support hardware from the Open Compute Project (OCP). VMware is providing contributions to OCP to facilitate EVO RACK deployment.

~~~~

Sorry about the stream of consciousness approach to this. We got a deep dive on what’s in vSphere 6 but it was all under NDA. So this just represents what was discussed openly in keynotes and other public sessions.

Comments?


Fall SNWUSA 2013

Here’s my thoughts on SNWUSA which occurred this past week in the Long Beach Convention Center.

First, it was a great location. I saw a number of users I haven’t seen at SNWUSA ever before, some of which I have known for years from other (non-storage) venues.

Second, the exhibit hall was scantly populated. There were no major storage vendors at the show at all. Gold sponsors included NEC, Riverbed, & Sepaton, representing the largest exhibiters presenn. Making up the next (Contributing) tier were Western Digital, Toshiba, Active Archive Alliance, and LTO consortium with a smattering of smaller companies.  Finally, there were another 12 vendors with kiosks around the floor, with the largest there being Veeam Software.

I suspect VMWorld Europe happening the same time in Barcelona might have had something to do with the sparse exhibit floor but the trend has been present for the past few shows.

That being said there were still a few surprises in store, at least for me.  Two of the most interesting ones were:

  • Coho Data who came out of stealth with a scale out, RAIN (Redundant array of independent nodes) based storage cluster, with distributed, mirrored customer data across nodes and software defined networking. They currently support NFS for VMware with a management UI reminiscent of IOS 7 sans touch support. The product comes as a series of nodes with SSDs, disk storage and SDN. The SDN allows Coho Data to relocate front-end (client) connections to where the customer data lies. The distributed, mirrored backend storage provides redundancy in the case of a node/disk failure, at which time the system understands what data is now at risk and rebuilds the now-mirorless data onto other nodes. It reminds me a lot of Bycast/Archivas like architectures, with SDN and NFS support. I suppose the reason they are supporting VMware VMDKs is that the files are fairly large and thus easier to supply.
  • Cloud Physics was not exhibiting but they sponsored a break. As such, they were there talking with analysts and the press about their product. Their product installs as a VMware VM service and propagates VMware management agents to ESX servers which then pipe information back to their app about how your VMware environment is running, how VMs are performing, how your network and storage are performing for the VMs running, etc. This data is then sent to the cloud, where it’s anonymized. In the cloud, customers can use apps (called Cards) to analyze this data in the cloud, which can help them understand problem areas, predict what configuration changes can do for them, show them how VMs are performing, etc. It essentially is logging all this information to the cloud and providing ways to analyze the data to optimize your VMware environment.

Coming in just behind these two was Jeda Networks with their Software Defined Storage Network (SDSN). They use commodity (OpenFlow compatible) 10GbE switches to support a software FCoE storage SAN. Jeda Networks say that over the past two years,  most 10GbE switch hardware have started to support DCB in hardware and with that in place, plus OpenFlow compatibility, they can provide a SDSN on top of them just by emulating a control layer for FCoE switches. Of course one would still need FCoE storage and CNAs but with that in place one could use much cheaper switches to support FCoE.

CloudPhysics has a subscription based pricing model which offers three tiers:

  • Free where you get their Vapp, the management agents and a defined set of Free Card Apps for no cost;
  • Standard level where you get all the above plus a set of Card Apps which provide more VMware managability for $50/ESX server/Month; and
  • Enterprise level where you get all the above plus all the Card Apps presently available for $150/ESX server/Month.

Jeda networks and Coho Data are still developing their pricing and had none they were willing to disclose.

One of the CloudPhysics Card apps could predict how certain VMs would benefit from host based (PCIe or SSD) IO caching. They had a chart which showed working set inflection points for (I think) one VM running an OLTP application.  I have asked for this chart to discuss further in a future post.  But although CloudPhysics has the data to produce such a chart, the application shows three potential break points where say adding 500MB, 2000MB or 10000MB of SSD cache can speed up application performance by 10%, 30% or 50% (numbers here made up for example purposes and not off the chart they showed me).

A few other companies made announcements at the show. For example, Sepaton announced their new VirtuoSO, scale out hybrid reduplication appliance.

That’s about it. I would have to say that SNW needs to rethink their business model, frequency of stows or what they are trying to do at their conferences. However, on the plust side, most of the users I talked with came away with a lot of information and thought the show was worthwhile and I came away with a few surprises.

~~~~

Comments?

Peak server, the cloud & NetApp storage for AWS

I was at a conference a month or so ago and one speaker mentioned that the number of x86 servers being sold has peaked and is dropping. I can imagine a number of reasons for this and the main one being server virtualization. But this speaker had a different view and it seemed to be the cloud.

Peak server is here.

He said that three companies were purchasing over 1/2 the x86 servers these days. I feel that there should be at least four Google, Facebook, Amazon & Microsoft and maybe five, if you add in Apple.

Something has happened over the past year or so. Enterprise IT has continued along its merry way but the adoption of cloud services is starting to take off.

I have seen this before, with mainframes, then mini-computers, and now client-server. Minicomputers came out and were so easy to use and develop/deploy applications on, that people stopped creating new apps on the mainframe. Mainframes never died out, and probably have never really stopped shipping increasing MIPS every year. But the share of WW MIP installations for mainframes has been shrinking for decades and have never got going again.

Ultimately, the proprietary minicomputer was just a passing fad and only lasted about 25 years or so. It was wounded by the PC, and then killed off by proprietary Unix workstations.

Then it happened again, the new upstart this time was Windows Server and Linux. Once again it was just easier to build apps on these new and cheaper servers, than any of the older Unix servers. Of course there’s still plenty of business in proprietary Unix servers, but again I would venture to say that their share of WW installed MIPS has been shrinking for a long time.

Nowadays, the cloud is mortally wounding the server market. Server virtualization is helping a lot but it’s also enabling the cloud to eliminate many physical server sales. This is because new applications, new IT environments are being ported/moved/deployed onto the cloud.

Peak server means less enterprise networking, storage and server hardware

In this new, cloud world, customers need less servers, less networking and less enterprise class storage. Yes not every application is suitable to cloud deployment but that’s why there’s still mainframes, still Unix servers, and a continuing need for standalone, physical or virtual x86 servers in the enterprise. But their share of MIPs will start shrinking soon if it hasn’t already.

Ok, so enterprise data center share of MIPs will start shrinking vis a vis cloud data centers. But what happens to networking and storage. My view is that networking becomes software defined and there’s a component of that which operates on special purpose hardware. This will increase in shipments but the more complex, enterprise class networking equipment will flatline and never see any more substantial growth.

And up until yesterday I felt much the same about enterprise class storage. Software defined storage in my future, DAS and SSDs for the capacity and the smarts exist in software if at all. Today, most of the cloud and many service providers have been moving off enterprise class storage and onto DAS.

NetApp’s new enterprise storage in AWS

But yesterday I heard about NetApp private storage for the cloud. This is a configuration of NetApp storage installed in a CoLo facility with a “direct connection” to Amazon compute cloud. In this way, enterprise customers can maintain data stewardship/ownership/governance over their data while at the same time deploying applications onto AWS compute cloud.

This seems to be one of the sticking points to enterprise customers adopting the cloud. By having (data) storage owned lock/stock&barrel by the enterprise it seems much easier and less risky to deploy new and old applications to the cloud.

Whether this pans out and can provide enough value to cover the added expense of the enterprise class storage, only the market can decide. But this is the first time I can remember, where any vendor has articulated a role for enterprise class storage in the cloud. Let’s hope it works.

Image: PDP8/s by ajmexico